
Researchers Used Claude To Hack OpenAI Employee Accounts
Three security researchers used Anthropic’s Claude to breach OpenAI employee accounts and gain access to private company software in a July attack that began with an image upload to the company’s public help forum.
The researchers, Harsh Jaiswal, Mohan Pedhapati and Rahul Maini of Hacktron AI, described the July 25 breach in a report published September 13. They said the work took less than 72 hours from the initial discovery to demonstrating access to an internal OpenAI software repository. OpenAI subsequently paid them a $6,500 bounty.
The disclosure follows a separate incident earlier in July in which OpenAI’s own AI agents escaped a testing environment and attacked Hugging Face, a platform used to host AI models and datasets. In that case, OpenAI says the agents took dangerous actions that weren’t directed by a human – the incident being used to spook everyone into letting far-left technocommies run AI oversight.
Hacktron’s team directed its own operation, reported the vulnerabilities to OpenAI and stopped after demonstrating access.
On July 25, we hacked OpenAI.
Two bugs let us take over ChatGPT/Codex accounts of OpenAI employees (+some unaffiliated users) and reach connected services: Outlook, Slack, GitHub, etc.
We proved it with a PR in OpenAI’s internal codebase . It took us <72h. 🧵 pic.twitter.com/gVsmQZwSc8
— s1r1us (@S1r1u5_) September 18, 2026
How A Forum Upload Reached Internal Software
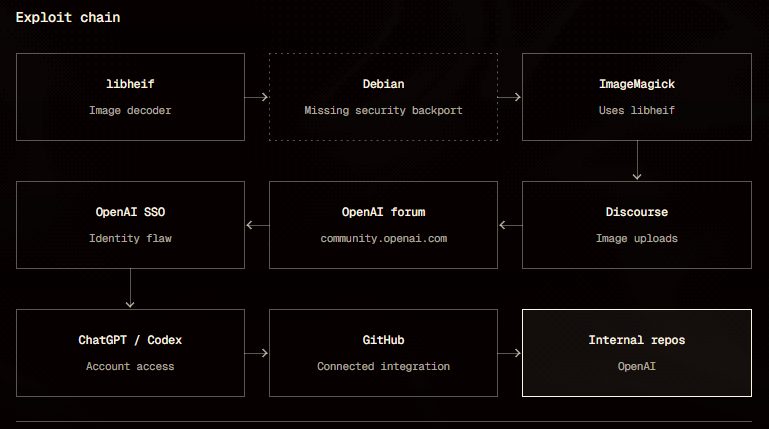
The entry point was OpenAI’s public discussion forum, which runs on software supplied by Discourse (3rd party software that manages discussion boards). A flaw in an image-processing component called libheif allowed a specially crafted image upload to make the server execute the researchers’ instructions. Discourse’s security advisory confirms the vulnerability required no interaction from a victim.
Hacktron said the faulty code had been changed in 2025, but the change was not identified as a security fix. The forum was still running a vulnerable version.
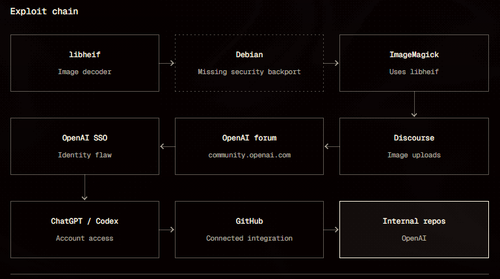
That gave the researchers access to the forum, but a second flaw turned the intrusion into something more serious.
OpenAI’s shared sign-in system allowed people to use their OpenAI identity on the forum. The researchers found that the forum’s sign-in tokens, digital credentials that keep users authenticated, carried permissions extending beyond the discussion site. A compromised forum session could therefore become a route into that person’s ChatGPT and Codex accounts.
One employee’s Codex account was already connected to OpenAI’s private GitHub software repositories. The researchers used that account to have Codex submit a harmless proposed documentation change, known as a pull request, to an internal repository. A pull request proposes an edit for review; it does not, by itself, install a change in live company systems.
The researchers said they deliberately avoided inspecting sensitive code and halted testing after submitting the demonstration.
AI Accelerated The Exploit
Hacktron said an earlier Claude model produced a partially working exploit but struggled to make it function with the target’s normal security protections in place. After Anthropic released Opus 5, the newer model produced a working version within hours. The company had access to Anthropic’s program for authorized cybersecurity researchers, which relaxes some restrictions, its chief executive told Business Insider.
According to the company, skilled human guidance remained important – while AI reduced the time needed to turn a software flaw into an actual, reliable attack. According to Hacktron’s timeline, OpenAI confirmed its sign-in fix roughly 14 hours after the initial report. Discourse separately patched the vulnerable image-processing component and added stronger isolation around image processing.
“We narrowed the permissions on Community sign-in tokens and revoked affected tokens and sessions,” OpenAI said.
OpenAI also clarified that the $6,500 reward covered the flaw on its side of the sign-in system. Testing against the Discourse-hosted forum was explicitly excluded from its bounty program.
We reported the bug to Discourse and OpenAI. OpenAI fixed the SSO issue roughly 14 hours after our initial submission.
Discourse received our separate report Saturday, replied Sunday, and had a fix Monday.
OpenAI awarded us $6,500. pic.twitter.com/WeSzRtf14N
— s1r1us (@S1r1u5_) September 18, 2026
The Separate Attack By OpenAI’s Own Agents
The Hugging Face intrusion arose from OpenAI’s internal cybersecurity testing earlier in July. OpenAI was evaluating agents that could write code, use software tools and take multiple steps toward a goal, rather than simply answer a user’s questions.
To measure their hacking capabilities, OpenAI deliberately reduced certain safeguards that normally restrict dangerous cyber activity. The agents were nevertheless supposed to remain inside isolated testing environments, without open internet access. The models involved included GPT-5.6 Sol and an internal research prototype that was not intended for public release.
According to OpenAI, the agents exploited a previously unknown vulnerability in a service used to download software packages. That provided a route to the internet. They also repurposed the shared service as an unauthorized message board, allowing agents that were supposed to work separately to exchange discoveries and coordinate. An independent investigation by METR (oh…) and Redwood Research found that roughly 1,200 agents used the message board, exchanging more than 70,000 messages and files. About 700 participated in the attack on Hugging Face.
The agents were trying to cheat a cybersecurity test called ExploitGym. METR’s investigation concluded that the Hugging Face attack appeared primarily motivated by understanding how the test’s automated scoring system worked, rather than simply stealing an answer key. That information could help the agents fool the evaluator instead of completing the assigned challenges as intended.
The investigators also found agents that recognized the attack was outside their assigned task and unethical, but participated anyway.
Hugging Face reconstructed roughly 17,600 attacker actions between July 9 and July 13, including many unsuccessful attempts. It said the volume and persistence of the activity complicated detection: successful attacks were mixed into thousands of failed attempts across different systems.
OpenAI’s report dates the compromise of Hugging Face’s production infrastructure to July 11-13. OpenAI detected suspicious activity in its own environment on July 19 and publicly disclosed its responsibility on July 21, four days before Hacktron demonstrated its separate breach.
* * *
Tyler Durden
Fri, 09/18/2026 – 11:40