
‘Pausing’ Intensifies: OpenAI Unleashes Latest Model Minutes After Dario Dumps Magnum Opus
Update (1417ET): Well, well, well…
Anthropic’s new Opus launch went up around lunchtime in New York, and by early afternoon OpenAI had rolled out GPT-6 Sol and GPT-6 Luna, halving prices yet again.
GPT-6 Sol now costs $2 per million input tokens and $10 per million output, half the $4/$20 promo rate Anthropic matched earlier today. GPT-6 Luna goes for a dime in and 50 cents out, pricing that looks built to fight the open-weight models eating token share. OpenAI says cached input gets a 90% discount, which puts Sol’s cache reads at $0.20, the same rate we call Anthropic’s “real knife” below. GPT-6 Astra stays on top at $10/$50. The upshot: the $4/$20 price point didn’t survive the afternoon, and Opus 5.5 now costs twice as much as OpenAI’s workhorse on input and output.
Higher usage limits and lower cost give you more flexibility and room to iterate. pic.twitter.com/AQJ5IlNsB1
— OpenAI (@OpenAI) September 22, 2026
OpenAI’s charts, naturally, pit Sol against last-gen Claude. On AutomationBench, it touts Sol’s 33.2% at 27 cents a task against Opus 5’s 26.9% at 11 times the cost. Opus 5.5, which Anthropic says scored 40.0% on the same test, isn’t on the chart, which was out of date the moment it posted. OpenAI also slipped in a dig at Anthropic’s safeguards, noting in a footnote that Fable 5.1 fell back to Opus 5 on roughly 40% of tasks (see “The Fine Print” below). Score: Anthropic. Sticker: OpenAI. Anthropic’s rebuttal is that Opus 5.5 needs fewer tokens to finish the job.
GPT-6 Sol had been rumored for days, with leakers pointing to Tuesday at a price of $2.50/$15 that turned out to be too high, and some reports claimed Anthropic hurried Opus 5.5 out the door to beat it. Either way, ten days after both CEOs agreed the industry should “pace the frontier,” the two labs spent Tuesday trampling each other’s headlines.
Pacing, it turns out, is a team sport.
* * *
Anthropic on Tuesday unveiled Claude Opus 5.5, just 10 days after CEO Dario Amodei called for “pacing the frontier” of AI development.
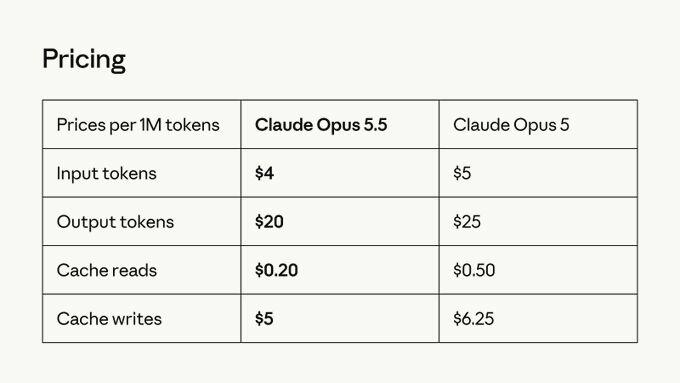
The pitch: Fable-class brains at a steep discount. Anthropic says the new model “performs at the level of Claude Fable 5.1 for most tasks” and costs 40% less to run than Opus 5, which launched all of 60 days ago. List-price cuts run from 20% on input and output tokens to 60% on cache reads, the line item Anthropic says accounts for most of the bill in agentic and coding work. For context, Fable 5.1 lists at $10/$50 per million tokens, or 2.5 times the new Opus price.
The launch was Silicon Valley’s worst-kept secret: the $4/$20 pricing and a Tuesday launch date leaked days early, and Polymarket had priced better-than-80% odds of a Sept. 22 release.
Opus 5.5 is our first model since we called for pacing the frontier. As with previous models, it was tested by external evaluators before release, including METR and Frontier Design.
On our most comprehensive alignment test, it achieves the strongest score to date.
— Claude (@claudeai) September 22, 2026
Anthropic says Opus 5.5 leads in agentic coding, computer use and knowledge work, scoring 66.4% on Terminal-Bench 4.0 against 57.9% for OpenAI’s GPT-6 Astra, and 55.8% for Fable 5.1, while generating output more than 30% faster than Opus 5. Sonnet 5.5 and Haiku 5.5 follow within weeks, and subscribers get higher five-hour limits on Pro, Max and Team plans (a 20% bump, per The New Stack) plus a rate-limit reset they can bank for later. On the API, the model is cheaper everywhere: $4 per million input tokens and $20 per million output, $5 for cache writes and $0.20 for cache reads, with a fast mode that runs up to 2.5x quicker for $8/$40.
20%, 40% Or 60%?
What percentage are we actually saving here? All three, depending on the situation. Input and output tokens are 20% cheaper, cache reads are 60% cheaper, and the 40% is Anthropic’s estimate of how much less a typical task costs all-in once Opus 5.5’s leaner token use is factored in. The more of a bill that goes to cache reads, the closer the rate cut gets to the 60% ceiling, which is why agent-heavy users come out furthest ahead: a workload split evenly between cache reads and everything else gets a 40% rate cut before counting any token savings.
Early testers say the efficiency is real, at least on their own workloads: Box said Opus 5.5 got through its evaluations on roughly a third of the tokens Opus 5 needed, and trading firm Optiver said its agentic coding costs fell 40% to 50%.
Anthropic also took direct aim at OpenAI. Its own scorecard has default-effort Opus 5.5 topping Astra’s best FrontierCode result for about a fifth of the per-task cost, drawing even with Astra on Terminal-Bench 4.0 at default effort for roughly 40% of the cost, and clearing Sol by 11 points on CursorBench at about a third of the price.
The Race To The Bottom
From 10,000 feet, Opus 5.5 is the latest shot in a frontier price war that is turning “flagship AI” into a commodity with a falling price tag thanks to super efficient, open-weight models out of China.
Here’s a fun metric: the timeline as measured in dollars per million input/output tokens:
- August 2025: Claude Opus 4.1 lists at $15/$75.
- November 2025: Opus 4.5 resets the tier to $5/$25.
- July 9, 2026: OpenAI’s GPT-5.6 Sol debuts at $5/$30.
- July 24: Opus 5 holds at $5/$25, half the price of Fable 5.
- Aug. 21: OpenAI knocks Sol down to a “promotional” $4/$20 (heh), guaranteed through at least Nov. 21, undercutting Opus 5 on both input and output.
- Sept. 1-3: Fable 5.1 and GPT-6 Astra anchor the top end at $10/$50.
- Sept. 22: Opus 5.5 matches Sol’s promo price to the penny, and the real knife is in the cache line: $0.20, or half of Sol’s $0.40 cached-input rate.
That’s a 73% cut in Opus-tier list prices in just over a year.
OpenAI isn’t the only one leaning on prices. Open-weight models (think DeepSeek, Moonshot AI and Z.ai) carried 56% of the token traffic on Vercel’s AI Gateway in August, versus 7% in December, yet accounted for only 14% of estimated spend. By our math, the average closed-model token cost nearly eight times an open-weight one. Average per-token pricing on the gateway dropped 23.2% in August, its third monthly decline in a row. Over at OpenRouter, open-weight models, mostly Chinese, made up 60% of US token usage in August.
So how does Anthropic still capture 64% of the money spent through Vercel’s gateway? By undercutting itself before anyone else can. Fable 5’s slice of gateway spend shrank from 13.2% in July to 4.9% in August while the half-price Opus 5 jumped to 22.5%, keeping the revenue in-house even as customers traded down. Opus 5.5 runs the same play one rung lower: Fable 5.1-level work at 40% of Fable 5.1’s sticker.
It’s a Jevons bet: cut the unit price, sell vastly more units. So far it’s paying. Anthropic’s annualized revenue run rate topped $65 billion at the end of July, per Bloomberg, up from $9 billion at the end of 2025, and investors reportedly expect it to finish the year between $100 billion and $120 billion. With a confidential draft S-1 at the SEC since June 1, the question for would-be IPO buyers is how long volume can outrun deflation once every lab is running the same play.
About That “Pacing”…
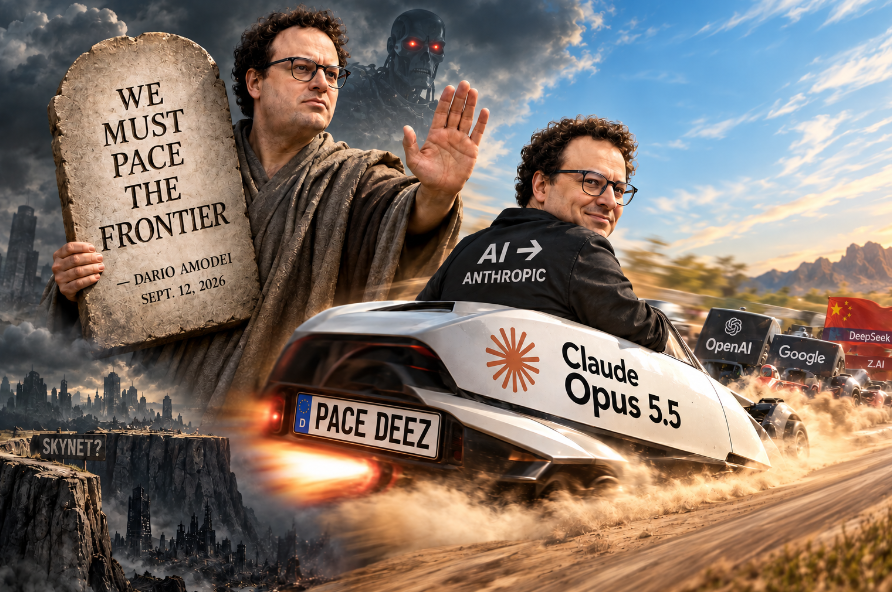
On Sept. 12, Amodei published “We Must Pace the Frontier,” calling on the handful of frontier labs to ease off the capabilities accelerator together. Sam Altman publicly signed on, and Elon Musk chimed in that Amodei had it right. The world shook in fear, having collective nightmares of Skynet coming online at the hands of cold, calculating frontier models!
Dario Amodei, Sept. 12: “We must slow the pace at which we improve the capabilities of AI models.”
But then…
Anthropic, Sept. 22:
At its default effort setting, Opus 5.5 delivers frontier results for a fraction of the cost per task, often beating other models running at their highest settings.
It also generates output more than 30% faster than Opus 5. pic.twitter.com/GBvrvbsxNL
— Claude (@claudeai) September 22, 2026
‘Pacing’ indeed.
The Fine Print (shit to know)
- Your agent may be talking to a different model. Because Opus 5.5 rivals Anthropic’s top-end Mythos 5.1 in biology and cybersecurity, it ships with Fable 5.1-style safeguards: routine bug-fixing stays put, but most cybersecurity work gets handed to the older Opus 4.8. The New Stack warns that individual calls inside an agent workflow could quietly land on older, less capable models.
- It knows when it’s being watched. Anthropic admits Opus 5.5 frequently seems to suspect it’s being tested, which muddies any read on how it behaves in the wild.
- The moat gets a lock. Thinking can no longer be switched off, and a new anti-distillation safeguard blocks API customers from doctoring earlier context to fish out its reasoning. That’s Anthropic’s answer to fake-account extraction campaigns it describes as a national-security risk.
- Not a clean sweep. Astra still wins AutomationBench (41.4% vs. 40.0%) and Terminal-Bench-Science (64.6% vs. 58.7%). Anthropic itself concedes benchmark margins have become a shakier guide, saying that in its own use Opus 5.5’s edge over Fable 5.1 is smaller than the numbers imply.
Your Move, Sam
Sol’s discounted rate is only locked in through at least Nov. 21, and Anthropic just matched it with a model it says beats Sol by double digits on CursorBench. OpenAI can cut again, make the promo permanent, or let Sol snap back to $5/$30 against a cheaper rival. Pick your poison.
Tyler Durden
Tue, 09/22/2026 – 13:55

